Models · Third generation · Instruct · Current
KW5-230M-instruct A Kiswahili assistant.
The third-generation assistant: works sums step by step, remembers what it was told, and says when it was not.
Fine-tuned from KW5-230M to answer from what it is given: a passage, an earlier turn, a sum to work. It is the release to use for Kiswahili questions over your own text, behind your own door.
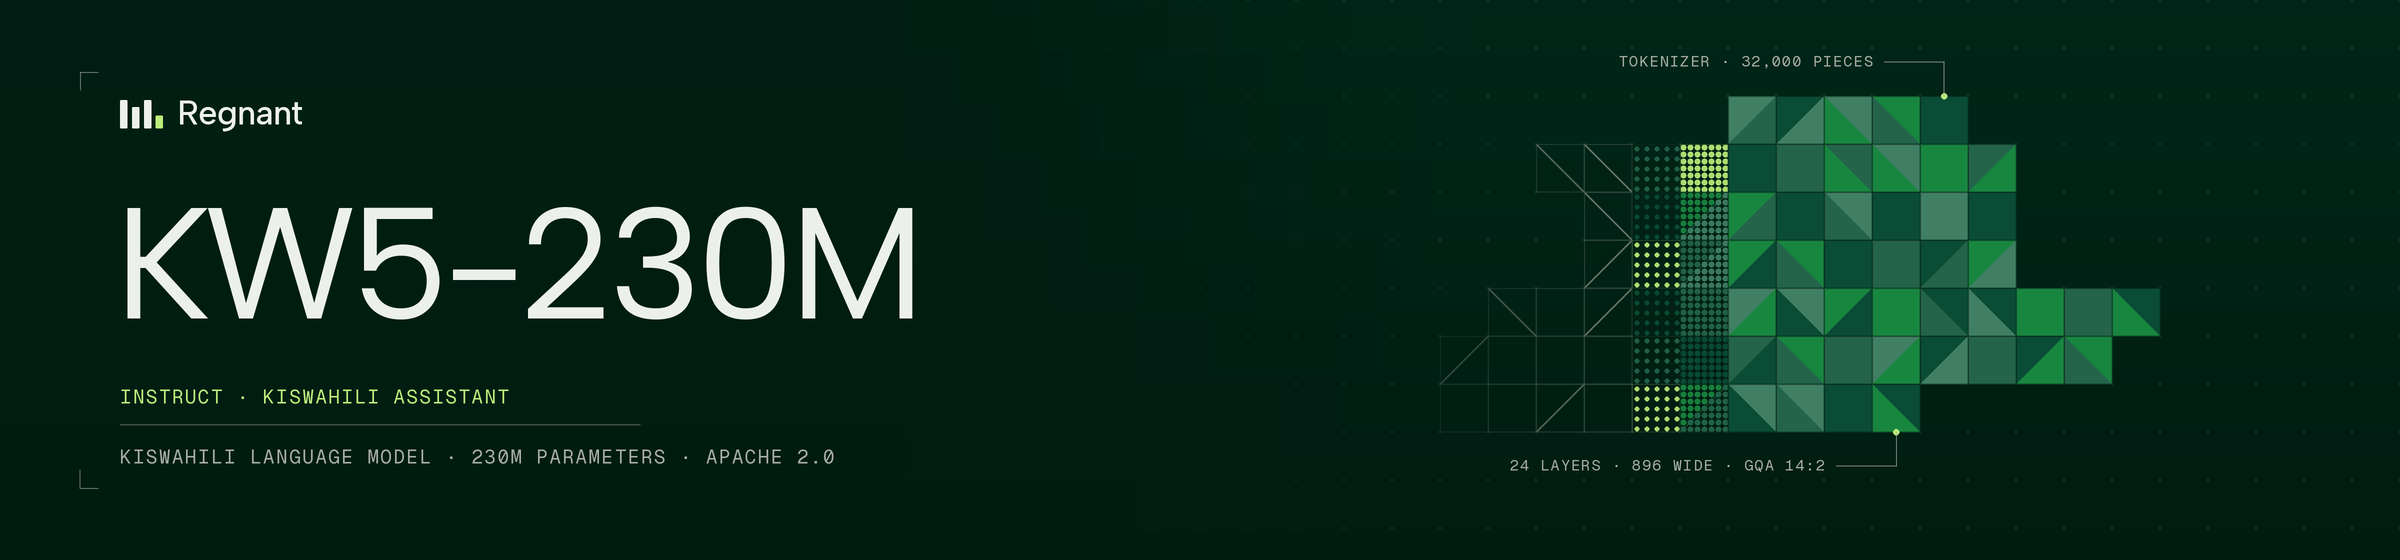
- 230.4M
- Parameters
- embeddings tied
- 24
- Layers
- 896 wide, feed-forward 2,432
- 2,048
- Context
- tokens
- Apache 2.0
- Licence
How it was trained.
- Base
- KW5-230M, 7.90B tokens of Kiswahili, decay completed
- Fine-tuning
- Full-parameter, two epochs of 204,483 conversations, 3,195 steps, context 2,048, at the base's rotary frequency
- Mix
- Curated instruction sets read source by source, grounded questions over real passages, generated arithmetic and long conversations, about 10,700 conversations translated by Gemma 4 26B-A4B, calibrated declines, and 10,213 verified replies of the first fine-tune
- Declines
- 10.4% of the mix; any conversation matching an evaluation prompt dropped (224)
- Forgetting
- Held-out Kiswahili drifted +0.054 nats against a tolerance of 0.35
- Hardware
- Kaggle TPU v5e-8, 15,792 s
How it measured.
- Bare arithmetic, n = 128
- 91.4% [85.3, 95.1] (bar 85; KW5-149M-instruct-r2 2.3%)
- Order of operations, n = 200
- 70.5% [63.8, 76.4] (bar 60)
- Recall a fact told 3 to 9 turns back, n = 80
- 98.8% [93.3, 99.8] (bar 70)
- Say a fact was never told, n = 40
- 82.5% [68.0, 91.3] (bar 60)
- Read a real passage, n = 250
- 58.4% [52.2, 64.3] (bar 60, missed)
- Answer from a list that changed, n = 40
- 5.0% (bar 50, missed)
- Belebele-sw, n = 900
- 35.6% [32.5, 38.7], chance 25%
- AfriXNLI-sw, n = 600
- 35.5%, does not clear chance
Seven of fourteen bars frozen before training are met. The second fine-tuning mix was built after the first was scored on the same suite; the items were kept out by hash, but the suite's arithmetic is no longer novel in frame, only in wording.
What it does well.
- Arithmetic worked step by step in a <mawazo> block, and only arithmetic
- Recalls what it was told across a conversation, and says so when it was not
- Declines when a passage does not hold the answer
- The best Belebele score of the small models compared, though not separated from the next
What it gets wrong.
- Keeps the first version of a list after it changes (2 of 40)
- Writes the wrong sum for many two-step word problems; 1 of 100 on AfriMGSM
- Declined 4 of 30 easy questions it should have answered
- Facts outside the prompt are unreliable at this size
- Safety sets (XSTest-sw, MultiJail-sw) not yet run
The family.
Run it on your own hardware.
The model card has the exact prompt format and the inference code.